AgentForge: Agent-Native Platform
AgentForge is a production platform for autonomous AI agents, not single model calls. An engineer defines an agent, gives it tools, safety rules, and a budget, pushes it live, and watches it run with guardrails already in place. Agents execute a think→act→observe loop with tool orchestration, and every run is governed by policy enforcement, budget caps, topic guards, and full tracing — the production layer teams usually rebuild from scratch. It ships safety enforcement (PII + policy checks at two checkpoints: block/warn/log), an LLM scope-guard classifier that confines an agent to an allowed topic, hard per-agent daily budget caps enforced before a run starts, an LLM-as-judge evaluation pipeline with version-to-version comparison (pass rate, latency, cost), per-agent RAG knowledge retrieval, OpenTelemetry tracing surfaced in Grafana with per-step tokens/cost, spend analytics by agent and day, BYOK multi-provider routing via LiteLLM (100+ providers), and multi-tenant record isolation — plus a Go auth service (JWT + OAuth), a Go CLI, and a Python SDK. I designed and built the entire system solo — backend, frontend, auth service, infrastructure, and CI/CD — deployed it to real AWS/EKS via Terraform, Helm, and a gated GitHub Actions pipeline, then executed a clean, cost-controlled teardown to $0, proving the whole lifecycle rather than just the demo.
Architecture
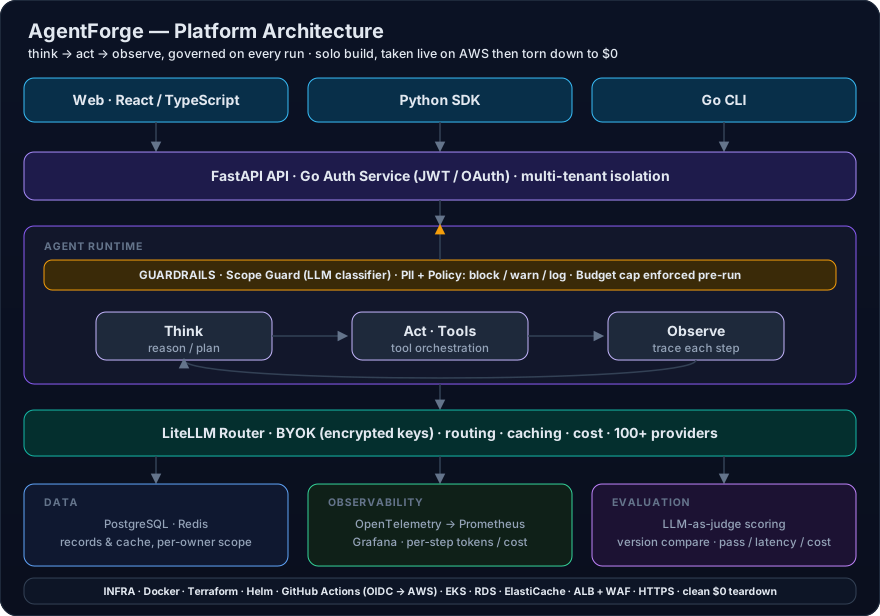
Tech Stack
Key Highlights
- Agent runtime: a think→act→observe execution loop with tool orchestration, governed by policy enforcement, budget caps, topic guards, and full tracing on every run
- Safety layer: PII + policy checks at two checkpoints (block/warn/log) and an LLM scope-guard classifier that confines an agent to its allowed topic
- Budget caps enforced before a run starts; live verification caught a caching layer that silently overcharged cache-hit responses and defeated the budget feature
- Evaluation pipeline: LLM-as-judge scoring with version-to-version comparison (pass rate, latency, cost) + per-agent RAG knowledge retrieval
- Full observability: OpenTelemetry traces in Grafana with per-step tokens/cost, plus spend analytics by agent and by day from real token counts
- BYOK, multi-provider via LiteLLM (100+ providers) so the platform never pays model bills; multi-tenant isolation scopes every record to its owner
- Taken fully to production on AWS/EKS — Terraform IaC, Helm, gated GitHub Actions pipeline, HTTPS + WAF — then a clean teardown to $0, proving the full lifecycle
- Solved live-only cloud failures: GitHub↔AWS OIDC federation, IAM/IRSA role scoping, an LB-controller certificate race, and recovering lost Terraform state with an S3 remote backend
- Solo build · ~4 weeks (Aug–Sep 2026) · ~16,800 LOC · 60 commits · 259 files · 160+ automated tests · 5 microservices + SDK + CLI